Building an AI Coding Agent: 6 Technical Lessons Learned
Building an AI coding agent looks simple at first: connect a large language model to a few tools and let it write code. In practice, the hard parts are the agent loop, tool design, context limits, safe execution, and testing. This article covers the six technical lessons that matter most, so you can avoid common mistakes and build an agent that works on real codebases, not just demos.
1. Start with a simple agent loop
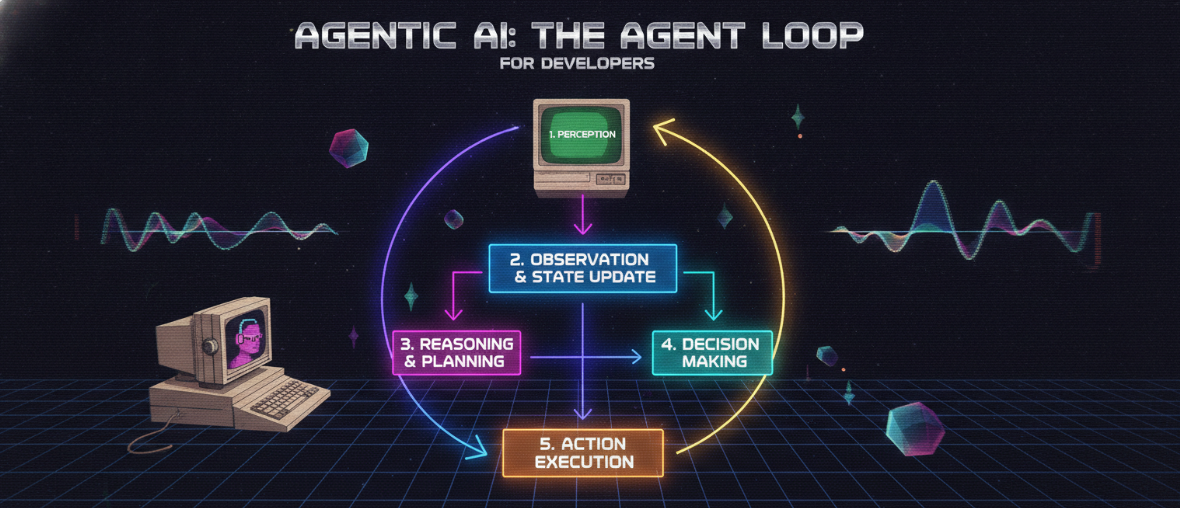
The core of an AI coding agent is a simple loop: plan, act, observe, repeat. The model decides the next step, calls a tool, reads the result, and continues until the task is done or a limit is reached.
Most early failures come from adding planners, memory, and multiple agents too soon. A basic loop is easier to debug, and you can see exactly where a run goes wrong. Add complexity only when a real failure demands it.
while not done and steps < MAX_STEPS:
    action = llm.decide(context)
    result = run_tool(action)
    context.append(result)
    steps += 1
2. Design small, clear tools
Tool calling works best when each tool does one job and has a precise description. The model chooses tools based on their names and descriptions, so vague or overlapping tools lead to wrong calls.
Start with a few tools such as read_file, write_file, and run_tests. Define exact input types, return clear error messages, and keep outputs short so they don't fill the context. A tool called do_task confuses the model, while read_file(path) does not.
{
  "name": "read_file",
  "description": "Read a text file from the project and return its contents.",
  "parameters": { "path": "string" }
}
3. Manage the context window on purpose
Context window management means deciding what the model sees at each step, because every extra token adds cost and can bury what matters. An agent that keeps every file and log in its context slows down, costs more, and starts making mistakes.
Send only what the current step needs. Trim long tool outputs, summarize earlier steps, and load files on demand instead of upfront. Keep the task goal and key constraints near the top so they don't get lost as the history grows. This approach is especially useful when working with AI Agents, where keeping context focused can improve efficiency and reduce unnecessary processing.
4. Sandbox all code execution
Sandboxing means running agent-generated code in an isolated environment, so a mistake cannot damage your system or leak data. An AI coding agent will sometimes write commands that delete files, install unknown packages, or expose secrets, even when it means well.
Run code inside a container such as Docker, with no access to your host files, limited network access, and CPU and time limits. Give the agent only the project folder it needs, and keep API keys and credentials out of its environment.
docker run --rm --network none --memory 512m \
  -v ./project:/workspace agent-sandbox pytest
5. Add guardrails and limits
Guardrails are rules that limit what an AI coding agent can do, how long it can run, and when it must ask a human. Without them, an agent can loop forever, burn through tokens, or make risky changes on its own.
Set a maximum number of steps and a token or cost budget for every run. Block dangerous commands, restrict which folders it can write to, and require human approval for actions such as deleting files, pushing code, or changing configuration. Log every tool call so you can review what happened.
BLOCKED = ["rm -rf", "git push --force"]
if any(b in command for b in BLOCKED) or steps >= MAX_STEPS:
    stop_and_ask_human()
6. Evaluate on real tasks, not demos
Evaluating an AI coding agent means testing it on real, repeatable tasks and measuring how often it succeeds, not judging it by one impressive demo. A demo shows the best case, while real repositories expose the failures.
Build a small set of tasks from actual bugs and features, such as fixing a failing test or adding a simple endpoint. Run the agent on each one, and record whether the tests pass, how many steps it took, and what it cost. If you're exploring what is JEV AI and how AI-powered coding agents work in practice, this kind of evaluation can help you understand their reliability, efficiency, and real-world performance. Review the logs from failed runs, fix the cause, and rerun the same set to confirm you improved things.
Conclusion
A reliable AI coding agent comes from good engineering basics, not from a bigger model alone. Keep the loop simple, design clear tools, control the context, sandbox execution, set guardrails, and test on real tasks. These six habits turn a fragile demo into something you can trust on a real codebase.